视频 · Seedance 2.5
静态人像驱动的连续镜头表演迁移
将用户提供的静态图像外观与参考视频中的表演、镜头运动和音频结合,生成一段保持人物身份稳定的写实电影感视频。
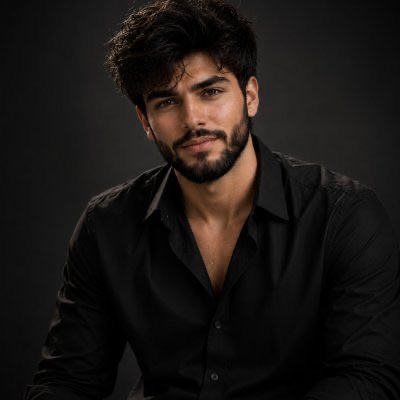 Zayan@HustleXR
Prompt
时长:30秒,单个连续镜头,照片级写实,电影感。

素材来源——严格区分:
- 图像1 = 唯一的视觉/摄影内容来源(100%)。输出中所有可见外观的像素均源自图像1:主体和整个场景,包括背景。
- 视频1 = 仅作为动作来源。它不提供任何外观、身份、背景、颜色或灯光,只提供动作、时机和摄影机运动方式。

关键要求——画面干净,零标注:
最终视频不得包含任何形式的图形标注——不得有网格线、辅助线、追踪线、十字线、定位标记、线框、动作捕捉或骨骼叠加层、水印、时间码或文字叠加。参考素材中出现的此类标记仅为制作辅助线;只渲染底层干净的摄影内容。

身份(取自图像1,锁定):
主体完全由图像1定义——面部、骨骼结构、肤色、眼睛、头发、体型、年龄和服装均严格依照图中所示。从第一帧到最后一帧,始终保持外观锁定且稳定:不得变形、不得出现特征漂移,也不得与视频1中的任何人物混合,即使在快速或极端动作期间也如此。画面中的表演者始终是图像1中的主体。

表演/动作(取自视频1,精确转移):
提取视频1中主体的动作,并原样应用到图像1中的主体。这包括所有身体动作、手势、姿势、重心变化、面部表情、细微表情、眨眼、眼球运动、嘴唇动作(完整对口型)、时机和节奏。转移表演,而非表演者——精确复现视频1中的动作,同时外观始终有100%源自图像1。

背景——让图像1中的场景动起来:
为图像1的背景加入自然且符合物理规律的运动,使画面绝不显得像静止背景上移动着一个剪贴出的主体。所有适用的背景元素都应可信、连续地运动——例如摇曳的树叶、飘动的云、荡漾的水面、变化的光影、随风飘动的布料/头发、环境中的人群或交通、尘土、蒸汽或反射——具体依据图像1中实际出现的内容决定。这些运动是为增强真实感和氛围而生成的,并非复制视频1的背景。保持运动细微、连贯且自然,效果悦目真实,不得混乱或分散注意力。

摄影机(取自视频1,逐镜头匹配):
严格跟随视频1中的摄影机运动——精确复现每一次摇摄、俯仰、轨道移动、横向移动、变焦、推近、拉远、手持晃动、滚转和抖动,方向、速度和时机均须一致,使虚拟摄影机逐帧跟随参考画面。匹配视频1的构图、镜头和景深。

前景物体与遮挡:
主体前方的任何物体都必须配合相同的摄影机运动——以符合物理规律的方式移动、产生视差并随摄影机重新构图,始终保持正确的相对位置、比例和透视关系。主体绝不能穿过、裁切穿透、重叠穿透或故障式穿越前景物体;遮挡必须符合物理规律,并根据摄影机和表演动作的要求,由物体真实地挡住或露出主体的相应部分。所有物体都应保持稳定且锚定在正确位置。

音频:
精确遵循视频1的音轨,与画面完全同步。

输出:
电影感,照片级写实,焦点清晰,物理效果自然,灯光连贯并以图像1为准,画面干净整洁。
Duration: 30 seconds, Single continuous shot, photorealistic, cinematic.
SOURCES — STRICT SEPARATION:
- IMAGE 1 = the ONLY source of visual/photographic content (100%). Every pixel of
appearance in the output derives from Image 1: the subject and the entire scene,
including background.
- VIDEO 1 = motion source ONLY. It contributes no appearance, no identity, no
background, and no color/lighting — only movement, timing, and camera behavior.
CRITICAL — CLEAN RENDER, ZERO ANNOTATIONS:
The final video must contain zero graphical annotations of any kind — no grid lines,
guide lines, tracking lines, crosshairs, registration marks, wireframes, mocap or
skeletal overlays, watermarks, timecodes, or text overlays. Any such marks appear in
the references only as production guides; render only the clean underlying
photographic content.
IDENTITY (from Image 1, locked):
The subject is defined entirely by Image 1 — face, bone structure, skin, eyes, hair,
body type, age, and wardrobe exactly as shown. Keep this appearance locked and stable
from the first frame to the last: no morphing, no feature drift, no blending with any
person from Video 1, even during fast or extreme motion. The performer on screen is
always the subject from Image 1.
PERFORMANCE / MOTION (from Video 1, transferred exactly):
Take the motion of the subject in Video 1 and apply it exactly to the subject from
Image 1. This includes all body movement, gestures, posture, weight shifts, facial
expressions, micro-expressions, blinks, eye movement, lip movement (fully lip-synced),
timing, and pacing. Transfer the performance, not the performer — replicate Video 1's
movement precisely while the appearance stays 100% Image 1.
BACKGROUND — ANIMATE THE IMAGE 1 SCENE:
Bring the background of Image 1 to life with natural, physically plausible motion so
the frame never looks like a still with a moving cutout. Every applicable background
element should move believably and continuously — e.g. swaying foliage, drifting
clouds, rippling water, moving light and shadow, blowing fabric/hair, ambient crowd or
traffic motion, dust, steam, or reflections — appropriate to what actually appears in
Image 1. This motion is generated for realism and ambience; it is not copied from
Video 1's background. Keep it subtle, coherent, and grounded — pleasing and realistic,
never chaotic or distracting.
CAMERA (from Video 1, matched shot-for-shot):
Follow Video 1's camera exactly — replicate every pan, tilt, dolly, truck, zoom,
push-in, pull-out, handheld sway, roll, and shake with identical direction, speed, and
timing, so the virtual camera tracks the reference frame by frame. Match Video 1's
framing, lens, and depth of field.
FOREGROUND OBJECTS & OCCLUSION:
Any objects in front of the subject are subject to the same camera motion — they must
move, parallax, and reframe with the camera in a physically grounded way, maintaining
correct relative position, scale, and perspective throughout. The subject must never
pass through, clip, overlap, or glitch through foreground objects; occlusions stay
physically accurate, with objects realistically blocking or revealing parts of the
subject as the camera and performance dictate. Keep every object stable and properly
anchored.
AUDIO:
Follow Video 1's audio track precisely, fully synced to the visuals.
OUTPUT:
Cinematic, photorealistic, sharp focus, natural physics, consistent lighting anchored
to Image 1, clean uncluttered frame.
使用建议
使用建议:上传一张作为人物与场景外观依据的图像,以及一段提供动作、镜头和音频参考的视频;生成前确认拥有相关素材的使用权,并根据目标工具调整时长与输出规格。