Video · Seedance 2.5
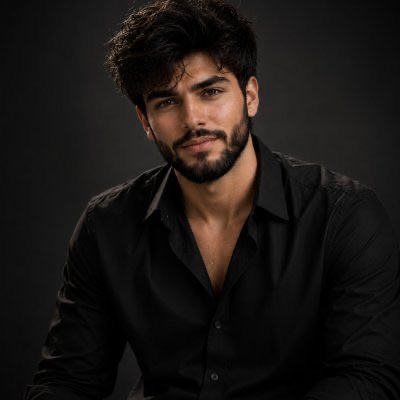
静态人像驱动的连续镜头表演迁移
将用户提供的静态图像外观与参考视频中的表演、镜头运动和音频结合,生成一段保持人物身份稳定的写实电影感视频。
 Zayan@HustleXR
Prompt
Duration: 30 seconds, Single continuous shot, photorealistic, cinematic.

SOURCES — STRICT SEPARATION:
- IMAGE 1 = the ONLY source of visual/photographic content (100%). Every pixel of
  appearance in the output derives from Image 1: the subject and the entire scene,
  including background.
- VIDEO 1 = motion source ONLY. It contributes no appearance, no identity, no
  background, and no color/lighting — only movement, timing, and camera behavior.

CRITICAL — CLEAN RENDER, ZERO ANNOTATIONS:
The final video must contain zero graphical annotations of any kind — no grid lines,
guide lines, tracking lines, crosshairs, registration marks, wireframes, mocap or
skeletal overlays, watermarks, timecodes, or text overlays. Any such marks appear in
the references only as production guides; render only the clean underlying
photographic content.

IDENTITY (from Image 1, locked):
The subject is defined entirely by Image 1 — face, bone structure, skin, eyes, hair,
body type, age, and wardrobe exactly as shown. Keep this appearance locked and stable
from the first frame to the last: no morphing, no feature drift, no blending with any
person from Video 1, even during fast or extreme motion. The performer on screen is
always the subject from Image 1.

PERFORMANCE / MOTION (from Video 1, transferred exactly):
Take the motion of the subject in Video 1 and apply it exactly to the subject from
Image 1. This includes all body movement, gestures, posture, weight shifts, facial
expressions, micro-expressions, blinks, eye movement, lip movement (fully lip-synced),
timing, and pacing. Transfer the performance, not the performer — replicate Video 1's
movement precisely while the appearance stays 100% Image 1.

BACKGROUND — ANIMATE THE IMAGE 1 SCENE:
Bring the background of Image 1 to life with natural, physically plausible motion so
the frame never looks like a still with a moving cutout. Every applicable background
element should move believably and continuously — e.g. swaying foliage, drifting
clouds, rippling water, moving light and shadow, blowing fabric/hair, ambient crowd or
traffic motion, dust, steam, or reflections — appropriate to what actually appears in
Image 1. This motion is generated for realism and ambience; it is not copied from
Video 1's background. Keep it subtle, coherent, and grounded — pleasing and realistic,
never chaotic or distracting.

CAMERA (from Video 1, matched shot-for-shot):
Follow Video 1's camera exactly — replicate every pan, tilt, dolly, truck, zoom,
push-in, pull-out, handheld sway, roll, and shake with identical direction, speed, and
timing, so the virtual camera tracks the reference frame by frame. Match Video 1's
framing, lens, and depth of field.

FOREGROUND OBJECTS & OCCLUSION:
Any objects in front of the subject are subject to the same camera motion — they must
move, parallax, and reframe with the camera in a physically grounded way, maintaining
correct relative position, scale, and perspective throughout. The subject must never
pass through, clip, overlap, or glitch through foreground objects; occlusions stay
physically accurate, with objects realistically blocking or revealing parts of the
subject as the camera and performance dictate. Keep every object stable and properly
anchored.

AUDIO:
Follow Video 1's audio track precisely, fully synced to the visuals.

OUTPUT:
Cinematic, photorealistic, sharp focus, natural physics, consistent lighting anchored
to Image 1, clean uncluttered frame.
How to use
使用建议:上传一张作为人物与场景外观依据的图像,以及一段提供动作、镜头和音频参考的视频;生成前确认拥有相关素材的使用权,并根据目标工具调整时长与输出规格。
Details
More from Zayan
-
Retro-Futurist Aviation Hero Portrait
-
Portrait blending fluid fantasy and modern vector art
-
Tropical Architecture Watercolor and Ink Travel Illustration
-
Noir Engineering Portrait Poster with Red Annotations
-
Swiss Modernist Car Speed Poster
-
Vermilion Mark: Neo-Japanese Mixed-Media Portrait
-
Cool-and-warm mixed-media art portrait
-
Vintage Car Ad Poster from Another Era